
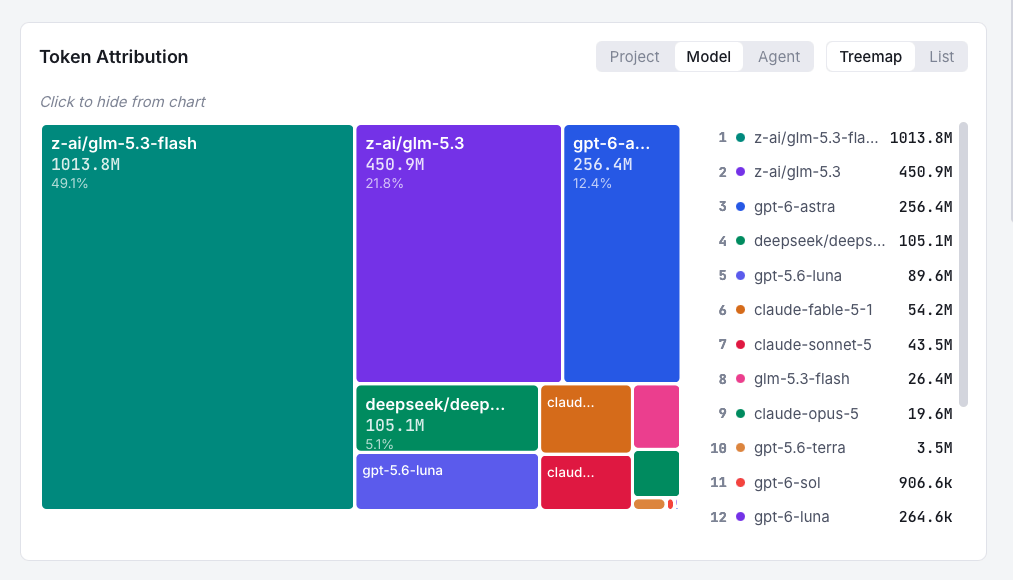
Zooming in on the models split specifically: The goal was to spend the whole month on GLM 5.3 Flash pictured in teal. Here’s what went well: Successfully spent the first half of the month on just that model. That model’s usage was well within our budget ($68, about 4k Wh of energy use / 365 grams of carbon emissions). The second half of the month didn’t go so well, with 1B tokens going to other models.
We chose the 'wrong' model for the prototype, and spent 450M tokens / $150 / 5k Wh of energy use almost overnight. We could have achieved similar results for most likely 5x less cost. Another unexpected hurdle was infrastructure availability issues. We noted degradation with the performance of GLM 5.3 Flash, having to switch to other models like Deep Seek V4.1 Flash and Qwen 3.8 Flash.
So technically this challenge was a failure. Only 50% usage on the target model, 1B out of 2B tokens. About 35 k Wh of energy use instead of 10. But we did learn a lot. Reflecting on this for October, here’s what will make it work: Constant, local usage measurement and reporting. Budgeting for experimentation. Making more concerted decisions about which prototypes are worth building.
For day-to-day developer work, it’s totally viable to focus on one or two flash-tier cheap models. A viable target is that the majority of AI inference work should be done with such efficient models, measured in cost or energy use rather than meaningless tokens. That’s the goal for October!
Source: Hacker News · Summarized by HeadlinesBriefing