
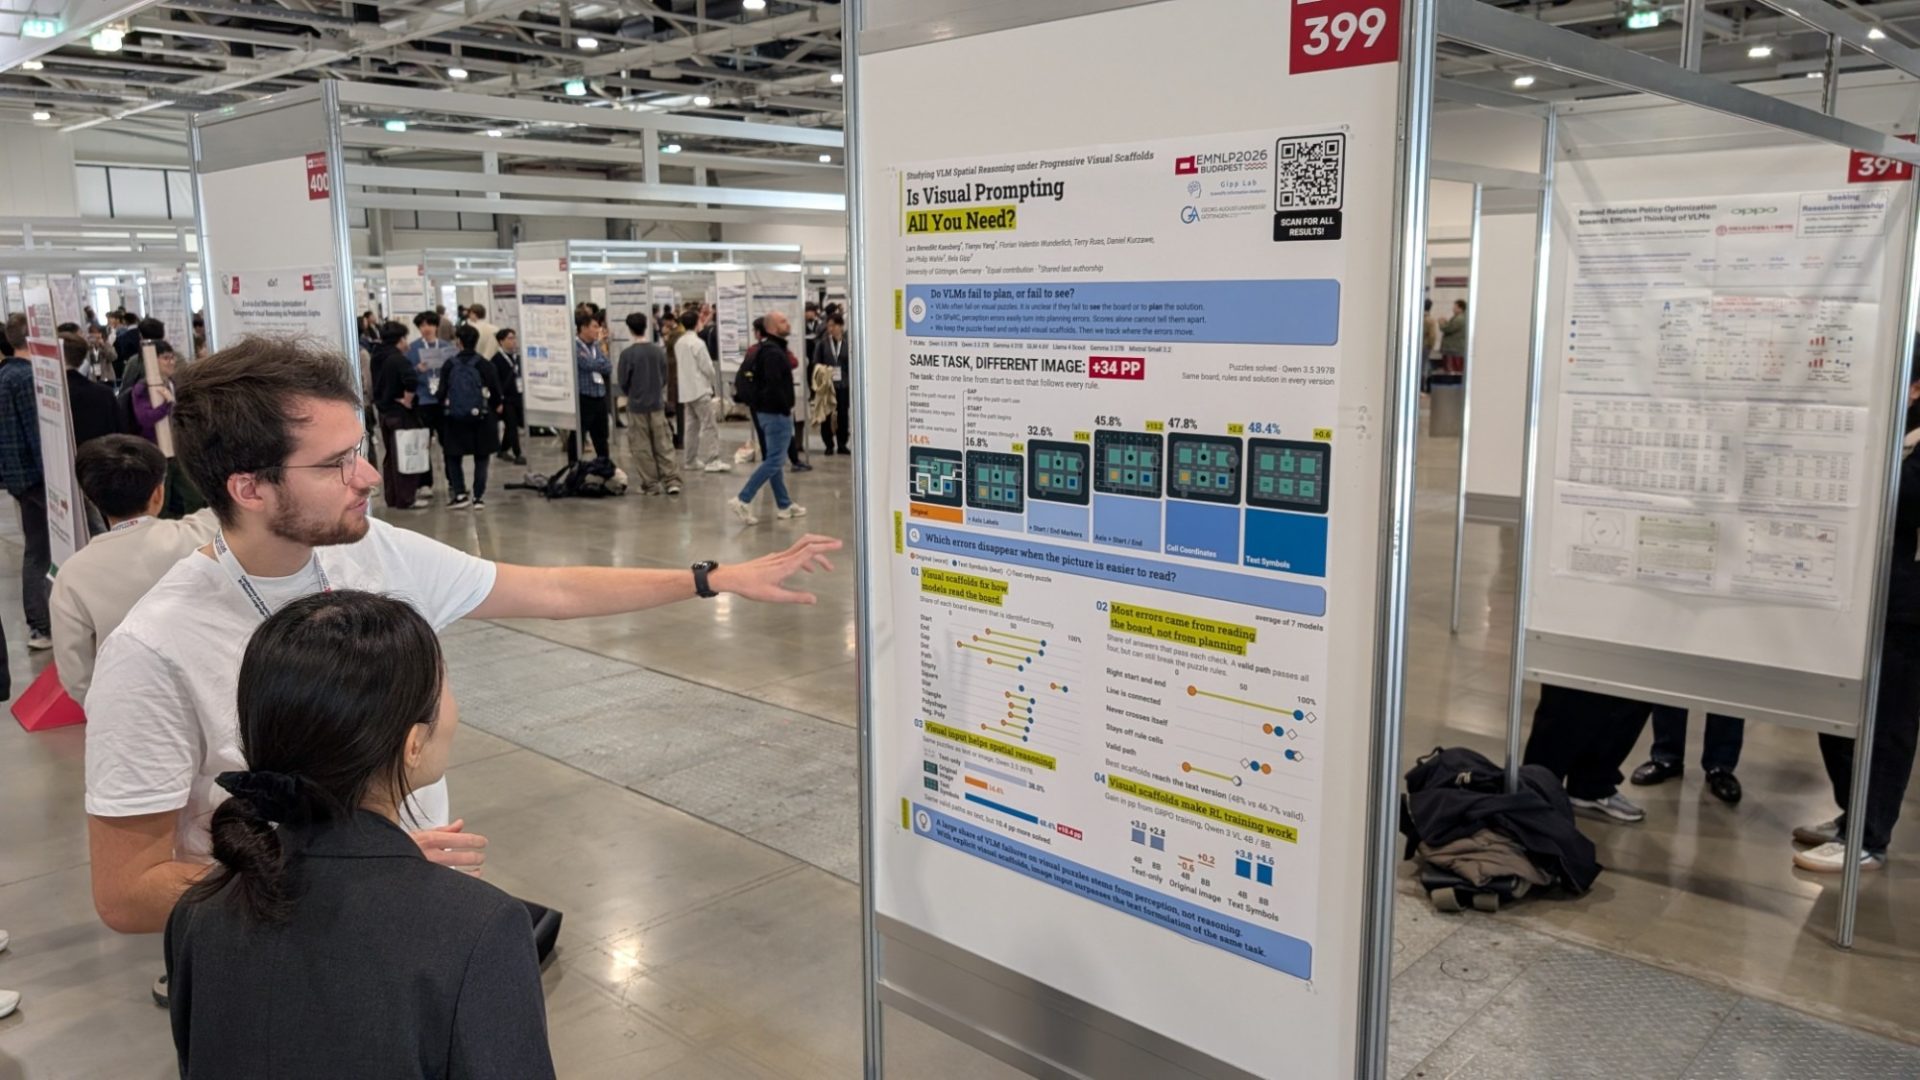
At EMNLP 2026 in Budapest, researchers presented findings suggesting that vision-language models fail more often due to image clarity than prompt wording. Using the SPaRC benchmark—1,000 grid puzzles inspired by *The Witness*—the team tested seven models. While prompt tweaks like examples or formatting shifted accuracy by only up to 5.2%, changing the image visualization caused swings as large as 34.0%.
For instance, Qwen 3.5 397B jumped from 14.4% to 48.4% accuracy simply by improving the drawing. The key was labeling specific elements the model missed, using terms consistent with the task. Adding arbitrary text did not help; only targeted annotations that corrected actual perception errors improved performance.
The study urges developers to prioritize image preprocessing over prompt engineering when vision models underperform.
Source: Towards Data Science · Summarized by HeadlinesBriefing