
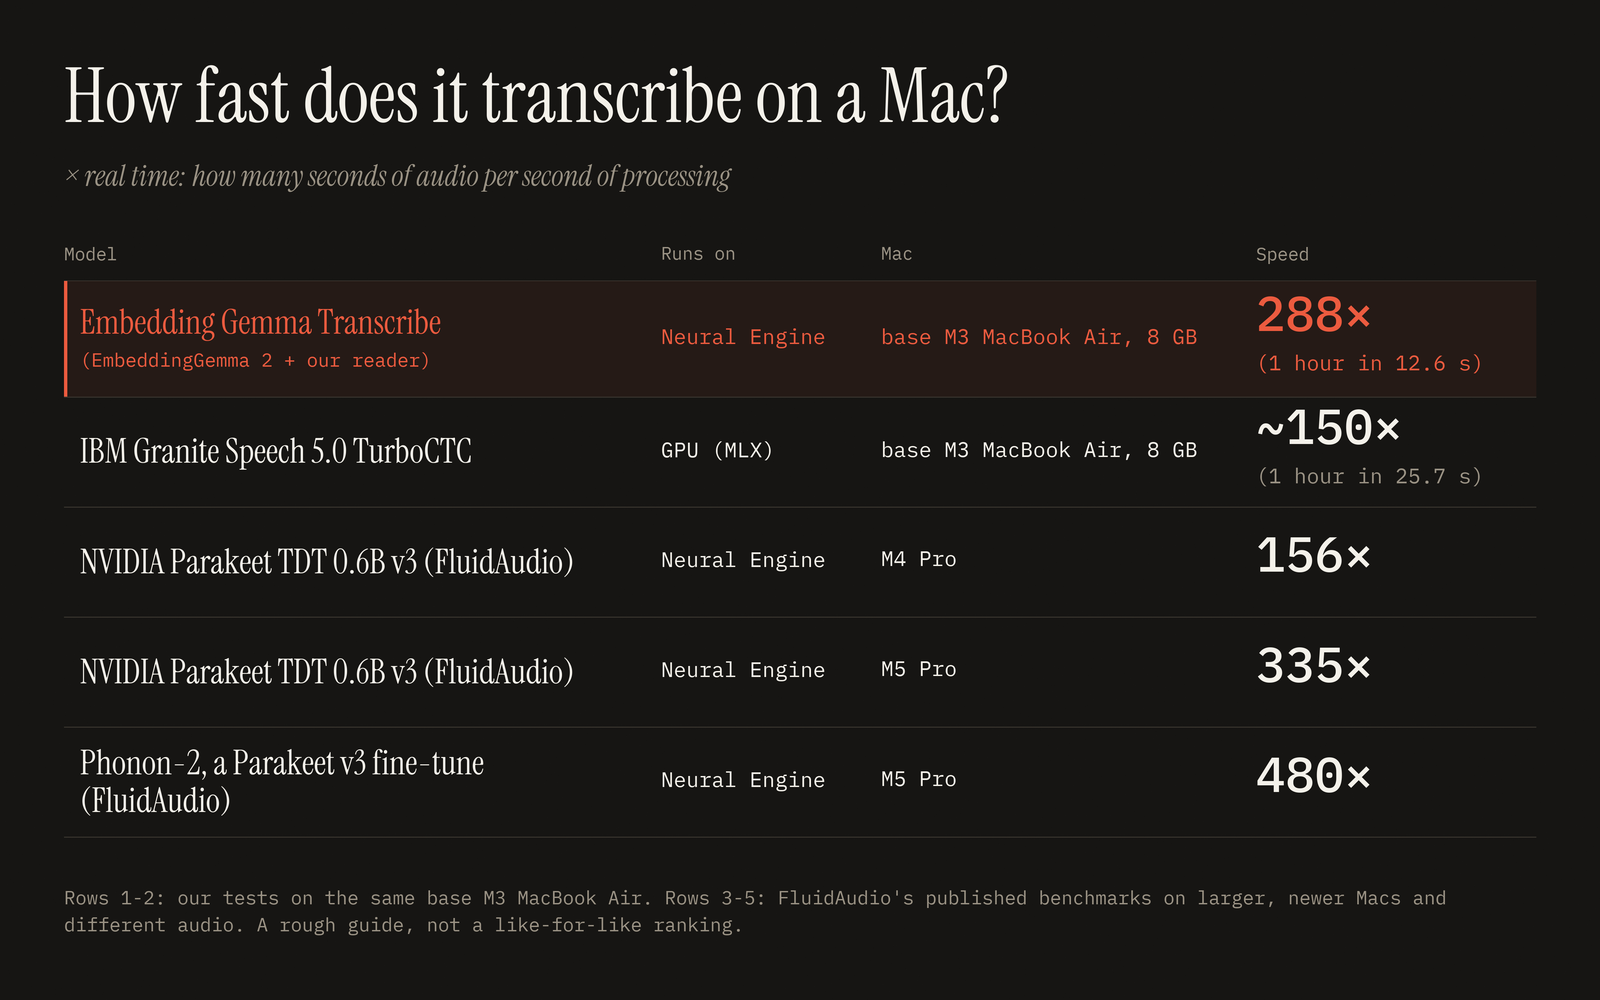
Google's Embedding Gemma 2 is an embedding model, and a new project has turned it into a speech-to-text tool. The developers report that it can transcribe an hour of audio in about 13 seconds on a base MacBook Air, entirely on the device.
The approach relies on the model's shared space for text, images, audio and video. Words spoken aloud land close to their written counterparts in that space, so the team read words directly out of it. The audio encoder stays unchanged. A small reader maps each short slice of audio into the model's text space, and the closest of roughly 229,000 English words is selected. A separate tiny model then adds punctuation and capitalization. Only the reader was trained, taking under two hours on 8×H100 GPUs using openly licensed English speech. The base model was never built for speech-to-text.
In the developers' own tests on the same base M3 MacBook Air, the approach transcribed an hour of audio in 12.6 seconds, a speed of about 288 times real time. That compares with 25.7 seconds for IBM Granite Speech 5.0 Turbo. The developers note that the other benchmarks cited were run on larger, newer Macs and different audio, so the figures are a rough guide rather than a direct ranking.
Accuracy is the current weak point. The word error rate is about 5%, compared with 2–3% for leading speech models. The team believes a better-trained reader can close the gap and plans that as the next iteration. The app is free for Mac running macOS 14 or later on Apple Silicon, with a 715 MB model that downloads on first launch. Users can drop in an audio file or hold Right Option to dictate into any app, and all processing runs on the Mac's Neural Engine so audio never leaves the machine.
Source: Hacker News · Summarized by HeadlinesBriefing