
Transformers excel at associative recall through attention mechanisms, but their quadratic overhead makes them impractical for applications like long-horizon reinforcement learning. Researchers needed RNNs that could match this memory capability without the computational cost. The m LSTM variant showed promise as the best RNN for associative recall, but struggled with noisy conditions.
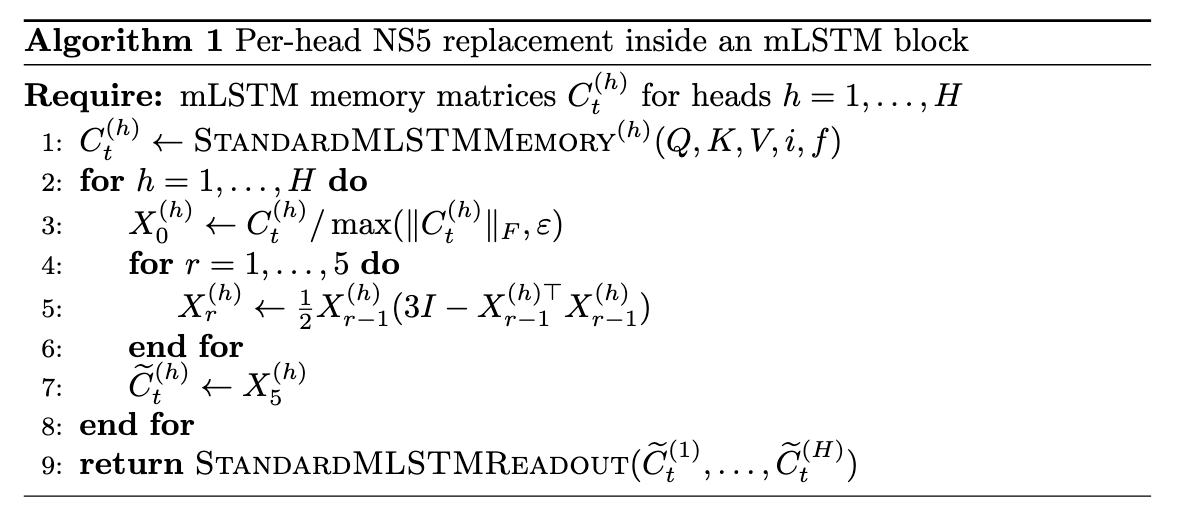
Paradigm-funded research explored noisy associative recall (NAR) as a more realistic test, where models must retrieve correct values while ignoring distractor tokens. Inspired by the Muon optimizer's momentum orthogonalization technique, the team applied similar principles to m LSTM's matrix memory during read operations.
Results demonstrated significant improvements across all test configurations. m LSTM orthogonalization achieved 87.5% accuracy versus 69.1% baseline for vocab-80/seq-512 tasks, with gains widening to +45.4 percentage points in the more challenging vocab-96/seq-1024 regime. The technique lifted previously failing models to substantially reliable performance.
Using five Newton-Schulz iterations with Frobenius normalization, the approach trades additional FLOPs for meaningful accuracy gains. While promising, the research cautions these synthetic task improvements may not directly translate to real-world benchmarks in larger models.
Source: Hacker News · Summarized by HeadlinesBriefing