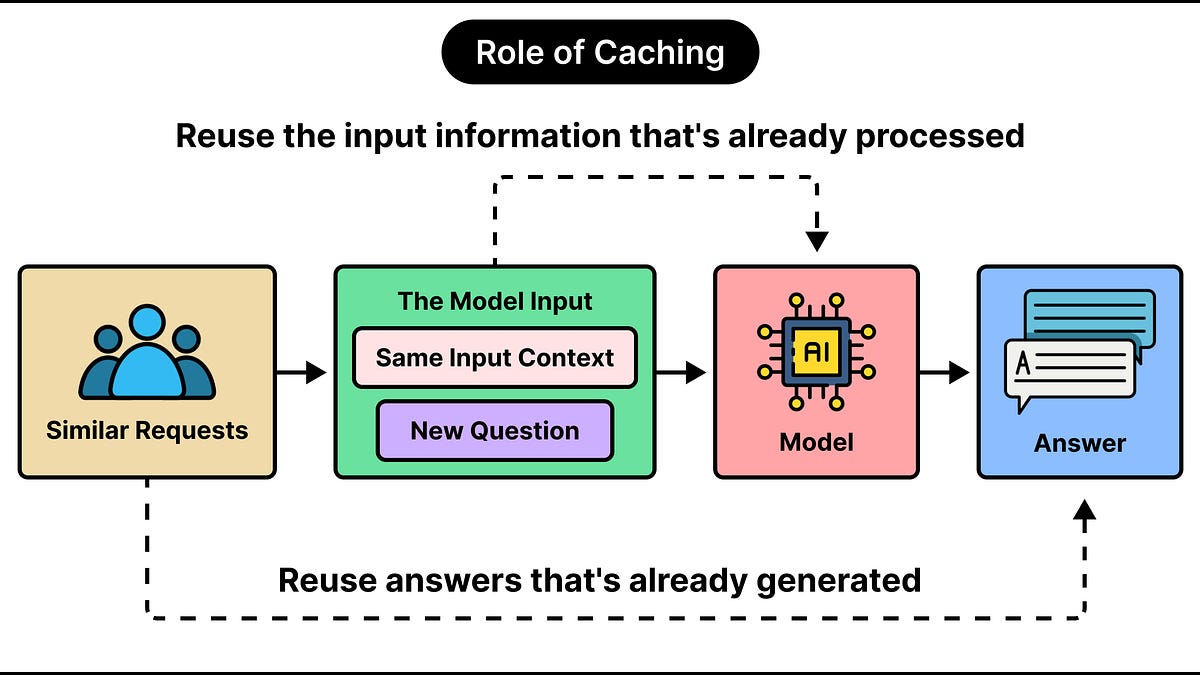
In this article, we’ll look at how LLM caching works in detail. Source: ByteByteGo · Summarized by HeadlinesBriefing Related articlesTuchel frustrated by 'freestyling' as NZ boss says England 'need to be better'Decision Models in Action: Build a Hybrid LLM WorkflowBotched final play sees Luka hesitate, LeBron missThe LLM Blindspot: Why Models Forget What’s in the Middle of Your PromptEngland booed off after limp Japan defeatMore from ByteByteGoWhy Shopify Migrated From React NativeHow Uber Built a Genie to Answer Questions CorrectlyEP229: 8 Chunking strategies for RAG-based agentsHow to Design for FailuresThe Terminator Problem: How Teaching an LLM One Bad Habit Can Change Its BehaviorLatest in DeveloperOregon lawmakers approve money to buy an iconic waterfall listed on Redfin · Hacker NewsDelays for Pull Requests and Webhook deliveries · Hacker NewsPatch the Planet: global response coordination as agents uncover vulnerabilities · Hacker NewsThe No Kings Takedown Is Why You Shouldn't Rent Your Megaphone from Zuck · Hacker NewsDuckDB 2.0.0 LTS "Cinnamon Teal" · Hacker NewsRelated briefingsDeveloper & AI 24-Hour BriefingDeveloper & AI 8-Hour BriefingHomeDeveloperLLM Prompt Caching Versus Semantic CachingSectionsHomePublic MarketsPrivate MarketsTech & GamesMobileDeveloperF1Sports