
SIFT (Scale Invariant Feature Transform) is one of the most widely known algorithms in computer vision. Its core objective consists of detecting object keypoints, generating descriptors for them, and matching the same objects across images. As the name suggests, SIFT is a scale-invariant algorithm, meaning that the same object can appear at different scales in a pair of images, and SIFT will still be able to successfully detect its keypoints. In addition, SIFT is rotation-invariant, making matching possible for rotated objects as well.
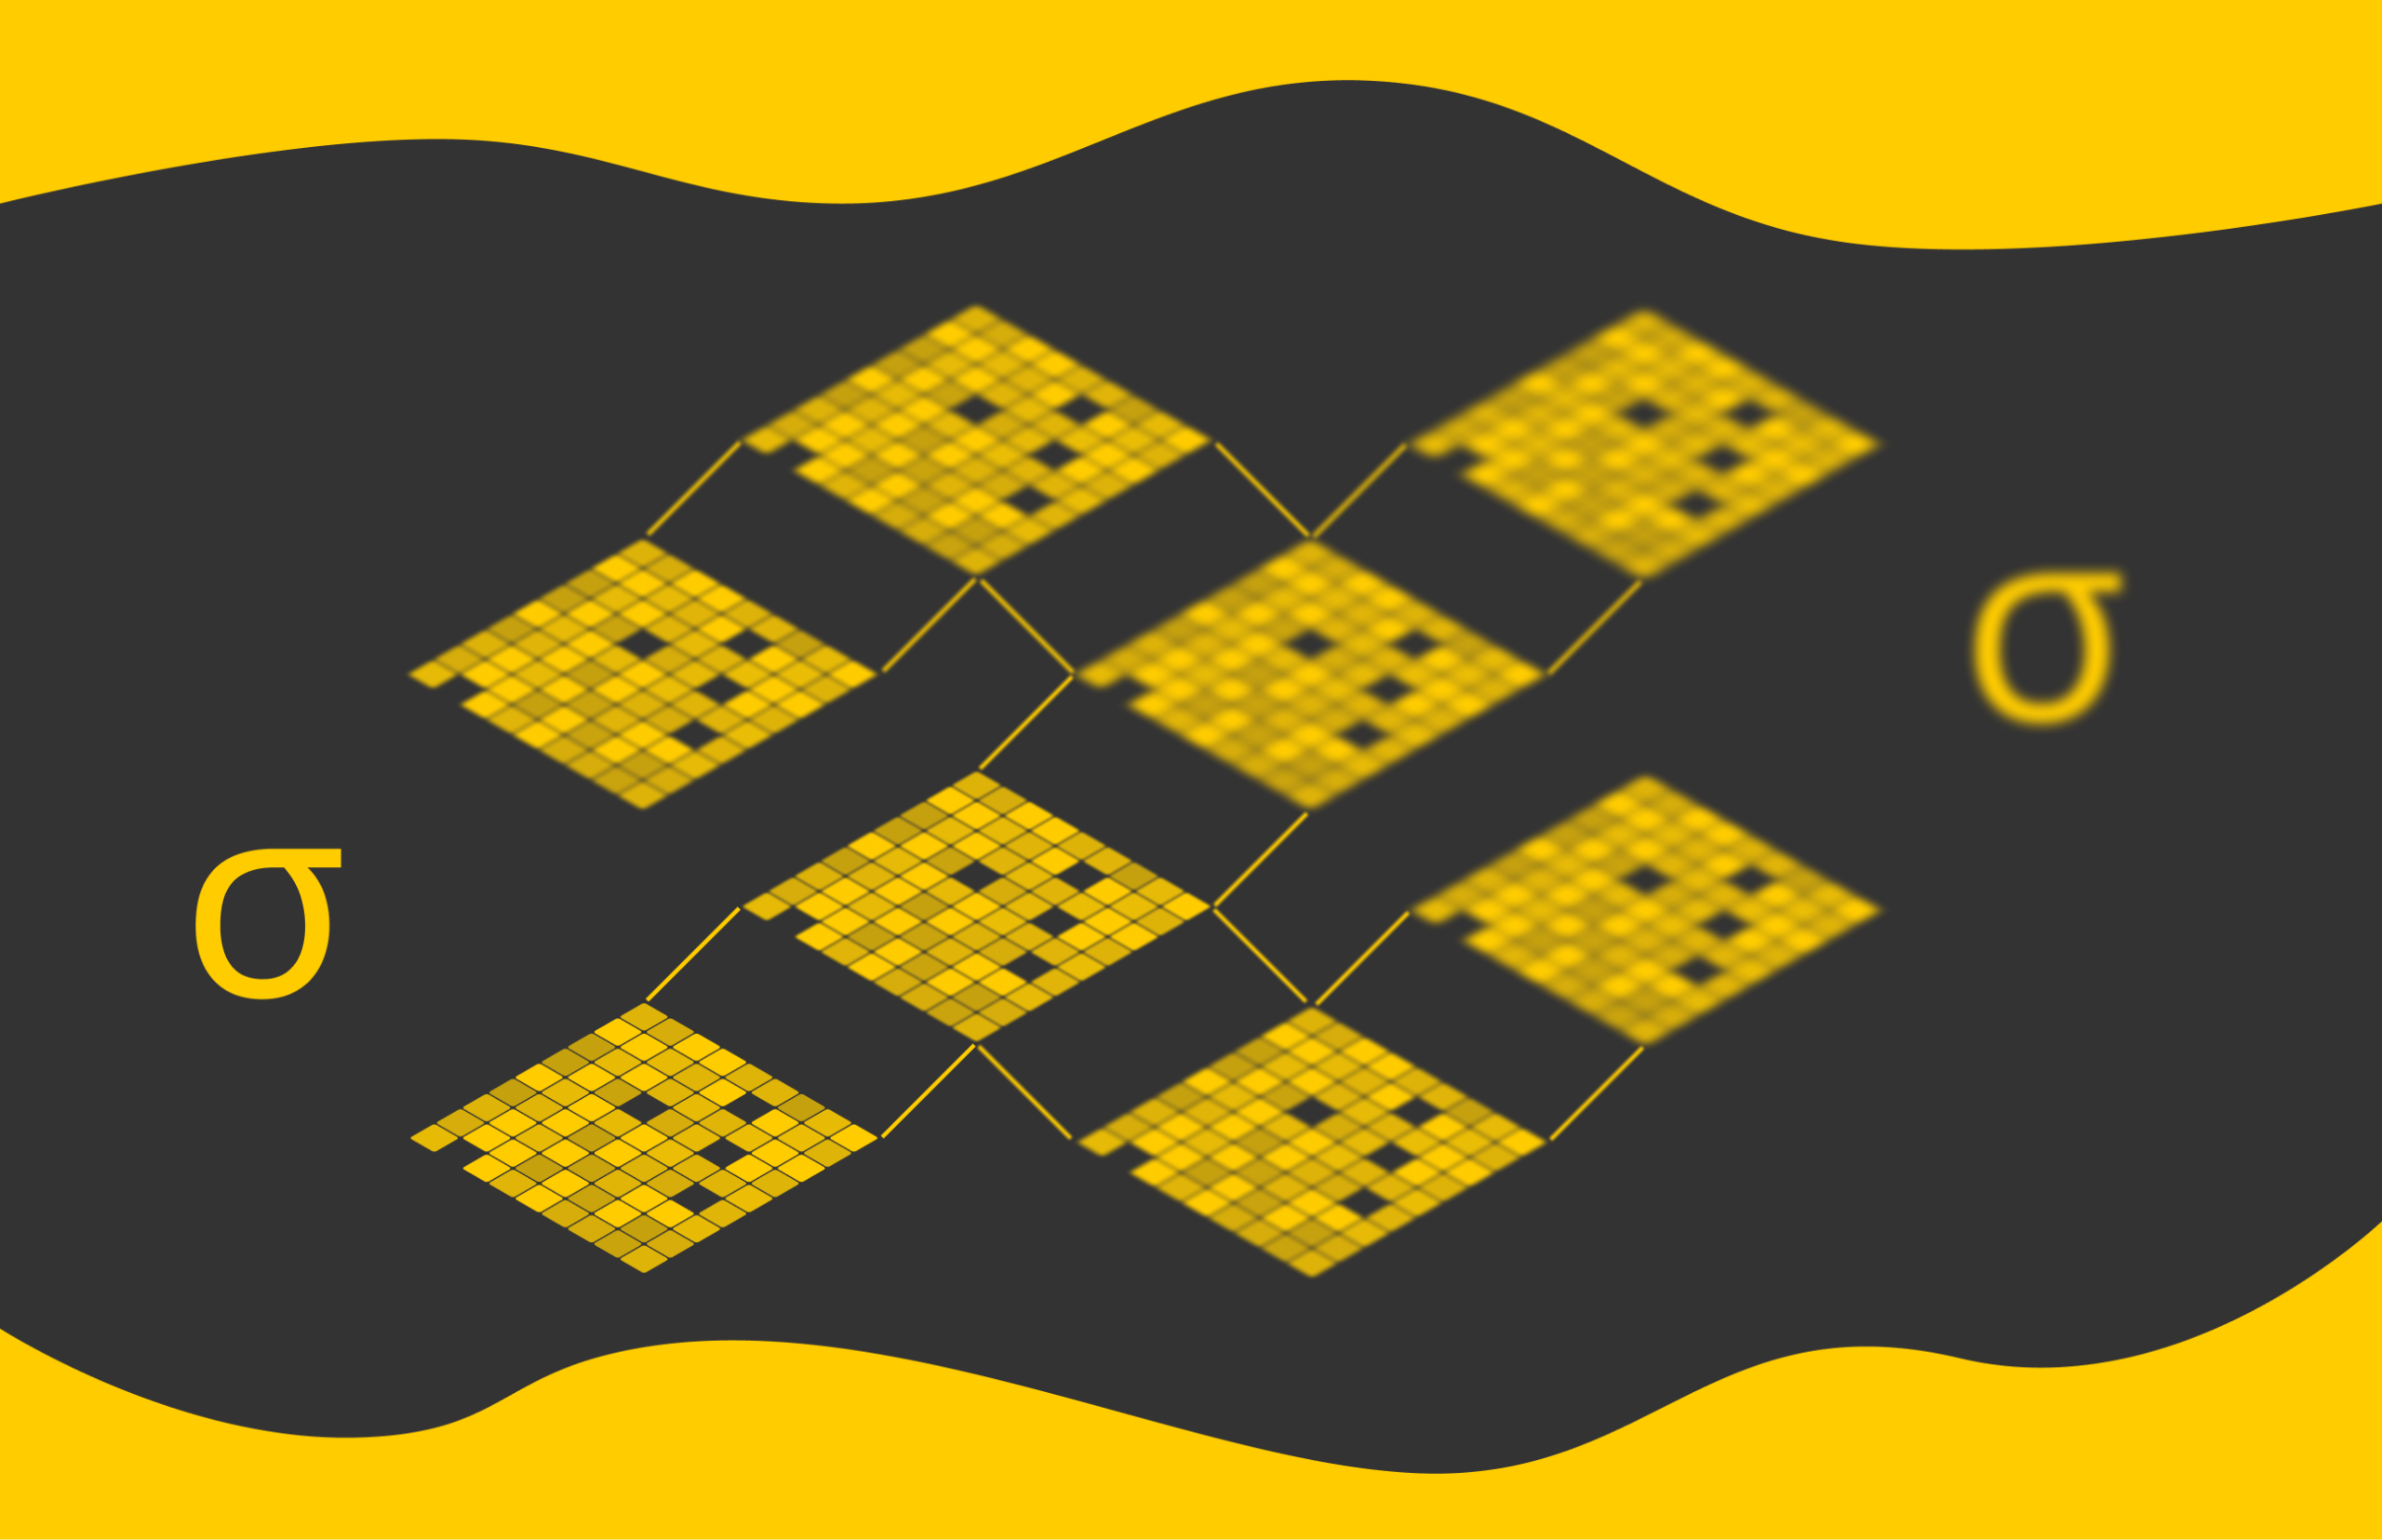
In its workflow, SIFT constructs several versions of the original image by applying resize and Gaussian blur transformations. First, with chosen values of k and σ1, SIFT constructs several versions of the original image by applying Gaussian smoothing with different standard deviations. This results in a sequence of images called an octave. Then SIFT computes the pairwise differences known as the difference of Gaussians (Do G). These differences highlight pixels with high intensity changes.
For each point in Di(x, y), SIFT examines its 26 neighbours: 8 adjacent points on Di level; 9 points directly above Di(x, y); 9 points directly below Di(x, y). If Di(x, y) is greater than all of its 26 neighbouring points, SIFT marks it as a maximum. If less, SIFT marks it as a minimum. This procedure identifies the strongest features. To account for different scale variations, the same process is repeated for an initial image reduced in width and height by a factor of two, constructing a new octave with σ values: σ2, k⋅σ2, k2⋅σ2, k3⋅σ2, where σ2 = 2σ1.
Source: Towards Data Science · Summarized by HeadlinesBriefing